An AI feature can be right almost every time and still get switched off, and the usage graph will not tell you why.
Two weeks after launch it looks like a small hill. A spike while everyone tries it, a plateau while the enthusiasts keep going, then a long slide. Support stays quiet the whole time. Nobody files a bug, because there is no bug. People tried the feature, could not tell whether the output was worth believing, and went back to doing the work themselves.
The standard explanations do not survive contact with that curve. The model was fine. Discoverability was fine. What failed is something most AI design writing never names, because it hides behind a metric everyone already tracks.
The thing users are pricing is not accuracy. It is verification cost: the time it takes a reasonable person to tell whether this particular answer is right. A correct output nobody can cheaply check has not saved anyone anything. It has moved the work.
Every pattern below exists to drive that number down. They are ordered so a product team can decide which ones to build this quarter and which ones can wait.
The feature was right and they stopped using it anyway
The arithmetic explains the abandonment curve better than any theory of user psychology.
An AI feature saves time only when the time to produce the answer plus the time to verify it comes in under the time to do the work by hand. Verification is the term teams forget to price. If an output takes four seconds to generate and eleven minutes to check, the feature has made the job worse, and it has done so while looking impressive in the demo.
Here is the part that catches good teams out. Verification cost is asymmetric in a way that punishes high accuracy. At 70 percent accuracy, people check everything and know they have to. At 95 percent, the failures are rare enough to be invisible and severe enough to matter, so the careful user still checks everything while the incautious user checks nothing and eventually gets burned. Both roads end with the feature switched off.
Raising accuracy from 95 to 97 percent barely touches that dynamic. Making the output checkable in fifteen seconds changes it completely.
So the reframe worth carrying into every design review is short. The question is not "how often is this right". The question is "how fast can a reasonable person tell". Which raises the obvious follow-up: tell by looking at what?
What users are actually judging
Three questions run underneath everything a person does with an AI output. They are rarely spoken aloud, and each one maps onto a different family of design patterns.
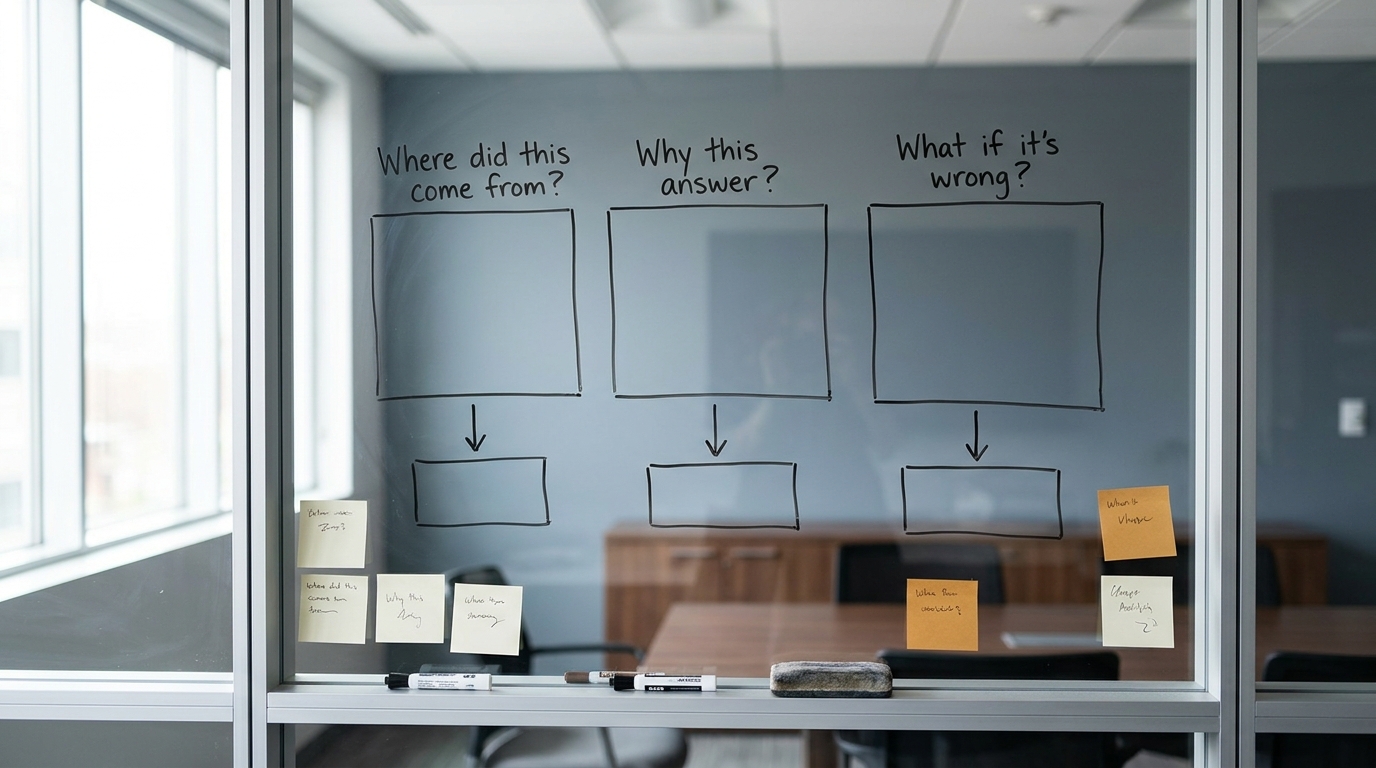
- Where did this come from? The user is trying to locate the answer in a world they already understand. A question about inputs, and transparency patterns answer it.
- Why this answer and not a different one? The user is testing whether the reasoning matches their own model of the problem. A question about process, and explainability patterns answer it.
- What happens if this is wrong? The user is pricing the downside before committing. A question about consequences, and review loops, reversibility, and honest failure states answer it.
Most product teams answer the first, gesture at the second, and ignore the third. That distribution is backwards for anything with real stakes attached. Someone deciding whether to act on a recommendation cares far more about what happens when it is wrong than about where the underlying data lives.
Write the three questions on the wall during design reviews. For any AI surface, a team should be able to point at the interface element that answers each one. If a question has no element, that is not a polish item for later. It is a hole where trust would otherwise go.
Transparency: show the work, not just the answer
Transparency patterns make the system's inputs inspectable. They are the cheapest trust work available and the most commonly done badly.
The pattern set is well established, and Google's People and AI Guidebook and Microsoft's HAX Toolkit both document versions of it:
- Inline citations with claim previews. The specific sentence is linked to the specific source, and hovering shows enough of the source to check without leaving the page.
- Source browsers. A panel listing everything the system consulted, so the user can see the shape of the evidence instead of one link at a time.
- Scope disclosure. A plain statement of what the system looked at and (the half everyone skips) what it did not. "Searched the last 90 days of tickets" tells the user how much weight to place on the answer.
- Action traces for agentic features. A readable log of what the system did, in the order it did it, when the feature takes actions instead of producing text.
- Provenance labels. Marking which parts of an output came from retrieved data and which were generated.
One rule separates the useful implementations from the decorative ones. A citation is only worth building if the user can check it in about one click without losing their place. Linking a sentence to the front page of a forty page document technically cites the source and practically does nothing, because the verification cost is unchanged. The claim preview matters more than the link.
Then there is citation theatre, where an interface shows five sources because five sources look rigorous, and none of them supports the specific claim sitting next to it. Users find this out once. After that they discount every citation the product shows them, including the good ones.
A product can pass every transparency test above and still lose the user at the next question.
Explainability: why this answer and not another
Transparency covers inputs. Explainability covers reasoning, and the two get conflated constantly, which is why so many products ship a citation list and wonder why users still hesitate.
The working patterns:
- Factor weighting. "Ranked highest because of response time and contract value" tells the user which dimensions drove the result and lets them notice when the weighting is wrong for their situation.
- Reasoning traces. The steps the system worked through, collapsed by default and expandable on demand.
- Counterfactuals. "This would change if the deadline moved" often beats the explanation itself, because it shows the user which inputs the answer is sensitive to.
- The rejected alternative. Showing what the system nearly chose, and why it did not, signals that a real comparison happened.
The design test for any explanation is whether it can change what the user does next. An explanation that cannot alter a decision is decoration, and users learn to skip decorative panels fast. Before building one, a team should be able to describe the specific case where a user reads the explanation and then does something different.
Explainability also has an uncomfortable property worth naming early, particularly for whoever is signing off on the engineering estimate. Rendering a reasoning surface is cheap. Keeping it truthful is not. An explanation generated separately from the answer, one that does not reflect the process that actually produced it, is a plausible story wearing the costume of a reason. A user who catches that discrepancy once will not trust the feature again. Build the explanation from the real mechanism or do not build it.
Confidence indicators, and the case against them
The most widely recommended trust pattern in the field is also the one most likely to backfire.
The conventional set is familiar. Percentage scores next to outputs, confidence bands like high, medium, and low, hedged language when the system is unsure, explicit uncertainty ranges on numeric predictions. Nearly every AI UX pattern library lists these as straightforward improvements.
They often are not, for a specific reason. A confidence number is only useful to someone who can calibrate it, and almost nobody can. Told that an answer is 82 percent confident, a user has no way to know whether that means "usually right" or "wrong one time in five, and catastrophically so". Worse, a confident looking number attached to a wrong answer does active harm, because it lends false precision to a mistake the user would otherwise have questioned. Displayed confidence that does not match real reliability transfers certainty the system has not earned.
The distinction worth designing around is between decorative confidence and behavioural confidence.
Decorative confidence puts a number in the corner and leaves the user to interpret it. Behavioural confidence changes what the product does. Low confidence routes the item into a review queue automatically. Low confidence suppresses the auto action and asks first. Low confidence shows two candidate answers instead of one, which communicates uncertainty in a form people read correctly without any training.
The rule that follows is narrow, and worth holding to. Show confidence only when it changes what the user should do, and prefer changing the product's behaviour over printing a number the user has to decode alone.
Note where behavioural confidence sends the doubtful cases, though. That destination is usually the least designed screen in the whole product.
Review loops and the disagreement path
Most AI features are designed for agreement. The user reads the output, accepts it, moves on. What happens when they disagree is usually a thumbs down icon, which is the least useful thing that could occupy that space.
A thumbs down captures dissatisfaction and throws away the correction. The correction is the part with downstream value, both for the user in front of you and for every future version of the system. Designing the disagreement path properly means treating it as a first class flow, not a feedback afterthought.
The pattern set:
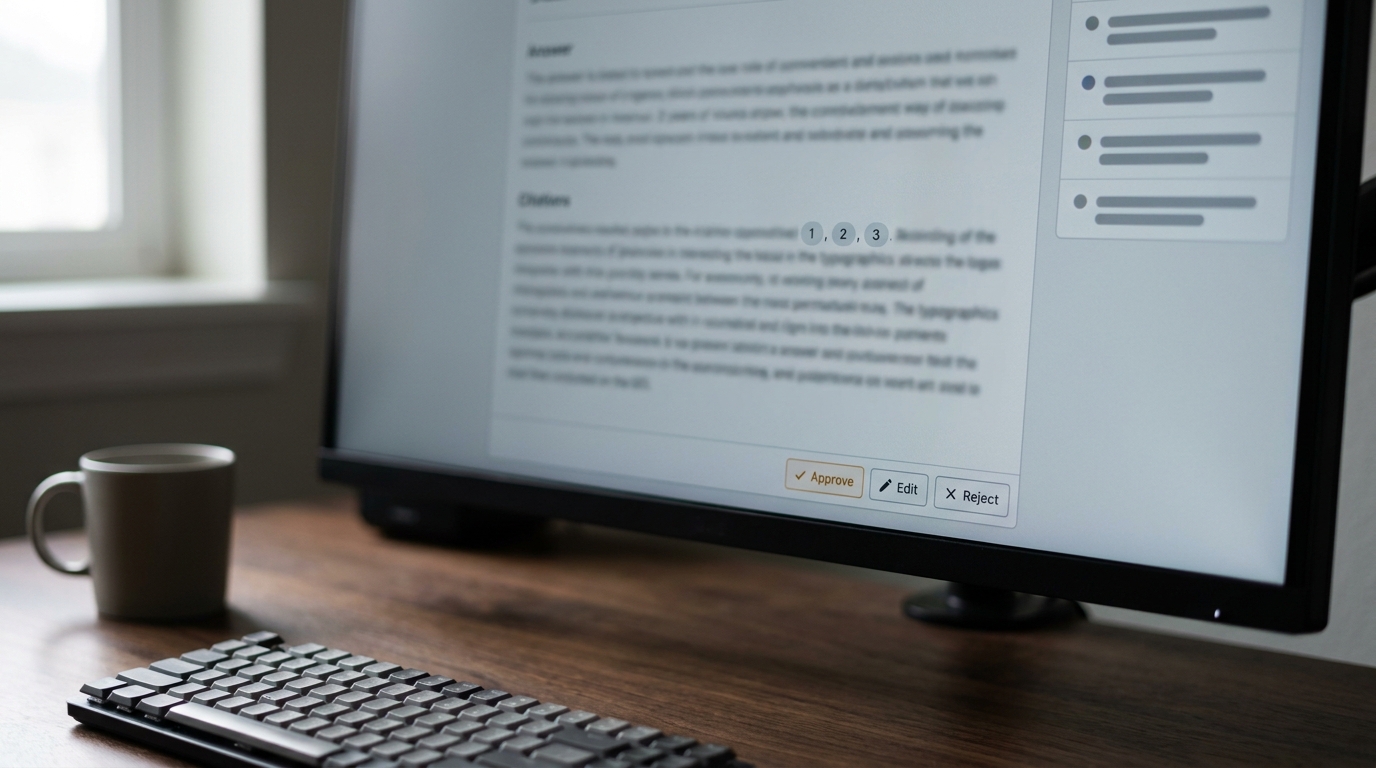
- Approve, edit, reject as a primary action set. All three visible at the same level, so editing is not hidden behind a rejection.
- Inline correction that captures the corrected value. When a user fixes a field, the system records what the right answer was, not merely that the previous one was wrong.
- Escalation with context attached. Handing off to a human should carry the input, the output, and the reason for the handoff, so the person receiving it does not restart from zero.
- Batch review. For high volume outputs, a queue that lets someone approve twenty items and interrogate the two that look odd.
- An audit trail. A record of what was suggested, what was accepted, and who changed what.
The rule here is economic. Correcting has to be cheaper than redoing, or the user will redo. If fixing a generated draft takes longer than writing one, people write their own and the feature dies without ever generating a complaint, which is the hill-shaped usage graph from the top of this article arriving by a different route.
Failure disclosure and graceful degradation
A system that never expresses doubt teaches people that its confidence carries no information anywhere. That lesson generalises across the whole product, which is why honest failure states protect trust in features they never touch.
Patterns that do this work:
- "I do not know" as a designed state. Not an error screen and not an apology, but a legitimate outcome with a sensible next action attached.
- Partial results with explicit gaps. "Found three of the five documents, two are still processing" beats a confident answer built on incomplete data.
- Declining out of scope requests plainly. Naming the boundary instead of improvising an answer beyond it.
- Data freshness disclosure. Saying when the underlying information was last updated, especially when the answer would change if it were newer.
The counterexample is easy to picture. An empty state saying "no results found" when the real situation is that a data source failed to load looks tidy and is a lie by omission. The user acts on an absence that is not real. One of those incidents costs more trust than a dozen visibly hedged answers.
Graceful degradation is the same idea applied to the whole feature. When the model is unavailable, slow, or working from partial context, the interface should say so and fall back to something useful.
Consent, control, and getting out
Once a feature stops producing text and starts taking actions, the trust question changes shape entirely. It is no longer "is this right". It is "what is this about to do on my behalf".
The relevant patterns:
- Granular consent before an action. Approval for the specific thing about to happen, not a blanket permission granted once during onboarding.
- Scope limits the user sets. Boundaries the person defines themselves, such as which systems the feature may touch or what value threshold requires sign off.
- Dry run and preview modes. Showing exactly what would happen before anything does.
- Undo and rollback. A real reversal, not a support ticket.
- A visible off switch. For anything running automatically, an obvious way to stop it without hunting through settings.
Reversibility carries more weight here than its position in the list suggests, because it buys more trust per unit of engineering effort than almost anything else on it. Trust is a bet on consequences, not a belief about accuracy. Lower the cost of being wrong and people will try the feature, which is the only way they ever accumulate the evidence to believe in it. An undo button does more for adoption than a percentage point of accuracy, and it is usually cheaper to build.
What to build first
Nothing in the pattern libraries tells a team where to start, which is why so many roadmaps either overbuild the trust layer on a low risk feature or ship a high risk one with none of it. The useful organising principle is the consequence of a wrong output.
Low stakes: drafts, suggestions, and anything the user reviews before it leaves the building.
- Transparency: show sources and scope.
- Undo, so a bad suggestion costs a click.
- That is enough. Ship it. A confidence score on a draft email is engineering effort spent on nothing.
Medium stakes: recommendations, prioritisations, and analysis that informs a real decision.
- Everything above.
- Explainability, because the user is being asked to accept reasoning, not text.
- A genuine review loop that captures corrections instead of sentiment.
- Behavioural confidence, where low confidence changes the flow instead of printing a number.
High stakes: actions on customer data, money, or anything with a regulatory shadow.
- Everything above.
- Granular consent gates on each action class.
- An audit trail that survives the session.
- Human approval required below a calibrated confidence threshold.
- Preview and rollback for every action the system can take.
For a product manager or a CTO, the point of the ladder is that trust work becomes a roadmap decision with a defensible shape instead of an open ended design ambition. It scales with consequence. Building the high stakes set onto a suggestion feature is overinvestment that delays the launch, and shipping the low stakes set on an action that moves money is the kind of decision that surfaces in a postmortem.
How to tell whether it worked
Trust is measurable, which is fortunate, because otherwise this whole discussion stays an argument between people with different intuitions.
Signals worth instrumenting:
- Correction rate over time. A rate that falls as the system improves means people are engaged with the output. A rate that falls while usage also falls means they gave up.
- Time from output to action. The clearest proxy for verification cost. If it is not dropping as users get familiar, the output is not becoming legible to them.
- Explanation expansion rate. How often people open the reasoning surface, and whether they still act after reading it.
- Escalation volume and resolution. Whether the handoff path is used, and whether it resolves anything.
- Return rate after a visible failure. What share of users come back after the system is wrong in front of them.
That last one is the real test, and almost nobody instruments it. Anyone will use an AI feature that has never failed them. Trust is what remains after a failure. A product with good disclosure, cheap correction, and easy reversal loses very few users to a single bad output. A product with none of those loses a lot of them.
Then there is the vanity metric, which is worth naming so it can be ignored. Thumbs up rate measures politeness and the willingness to click a button. It moves for reasons that have nothing to do with whether people rely on the feature when it counts.
Key takeaways
- Users abandon AI features they cannot verify, not features that are occasionally wrong. Verification cost, not accuracy, is the number to attack.
- Every AI output triggers three unspoken questions: where did this come from, why this answer, and what if it is wrong. Each one needs a specific interface element.
- Citations only help when the user can check them in about one click. Explanations only help when they can change a decision.
- Prefer behavioural confidence, where low confidence changes what the product does, over a decorative percentage the user cannot calibrate.
- Design the disagreement path deliberately. Correcting must be cheaper than redoing, and the correction is worth capturing.
- Match the depth of the trust layer to the consequence of a wrong output, and measure whether people come back after the system fails in front of them.
Where this leaves your roadmap
That hill-shaped usage graph is not a verdict on the model. It is a verdict on how much design work sits between the output and the person who has to decide whether to believe it. Close the gap and the same feature, at the same accuracy, gets used.
Deciding which patterns your own features need is a scoping problem before it is a design problem. It depends on what a wrong output costs in your product, which surfaces already carry that risk, and how much of the trust layer exists today.
If that is the decision in front of you, our Discovery Sprint is built for it. In one week we map your AI surfaces against the stakes ladder above and hand back a concrete build order, so the trust work lands on the features that need it and skips the ones that do not.