The fourth revision of the prompt is better than the third. The role framing is tighter, the output schema is explicit, the few-shot examples have been swapped for ones that actually match the edge cases. Somebody spent a good afternoon on it.
Nobody in that thread has asked whether the thing being prompted should exist.
Of the AI ideas that reach us, roughly nine in ten should never have been built. Not because they were badly executed. Because nobody applied a test that would have taken an hour, and the cheapest way to avoid that test is to spend the afternoon on the prompt instead.
That is the shape of most AI failure inside companies right now. Not a model that underperforms, not a data pipeline that breaks, not a security review that drags. An idea that was never examined, wrapped in enough craft to look like progress, moving steadily toward a build that will not change anything. The published failure rates for AI projects run somewhere between 70% and 95% depending on who is counting and what they count, and the interesting part is not the number. It is where in the timeline the failure actually happened.
If you own a roadmap or a budget, the expensive part of a bad AI idea was never the API bill. It was the quarter your team spent on it, and the three better ideas that sat in the queue while they did.
The prompt is the easiest thing to improve, so that is what gets improved
Prompt work has a property almost nothing else in this process has. It gives you feedback in seconds, it is visibly skilled, and it never requires telling anyone their idea is not worth doing.
Every other move at that stage is slower and more political. Checking whether the workflow has an owner means finding the owner. Establishing a before-state means somebody has to measure something nobody currently measures . Asking whether the business has already decided to tolerate this problem means asking a question with an uncomfortable answer. Rewriting the system prompt means opening a file.
So the file gets opened. The team iterates, the outputs improve, the demo gets better, and everyone involved can point at real work. The work is real. It is just not the work that decides the outcome.
The mechanism here is not laziness. It is that specification feels like commitment without being one. A detailed prompt reads as a considered decision about what the system should do, when what it actually encodes is an assumption about what the system should be for. Refine that assumption for long enough and it stops looking like an assumption.
A better prompt on a bad idea gets you a bad answer with more confidence and a nicer schema.
What prompt craft can and cannot fix
None of this makes prompt engineering unserious. Anthropic, OpenAI, Google, and Microsoft all publish good guidance on it, and the techniques work. Clear instruction, structured output, worked examples, and decomposition measurably change what a model produces.
What they cannot change is whether producing it matters. That question is upstream, it is answered once, and almost nobody schedules a meeting for it.
What "90% of AI projects fail" actually measures
Four widely quoted failure statistics are measuring four different things, and none of them means what the headline says.
The most-cited recent number comes from MIT's NANDA initiative, whose 2025 report on the state of AI in business found that roughly 95% of enterprise generative AI pilots produced no measurable return in the profit and loss statement. Gartner has published a separate forecast that at least 30% of generative AI projects would be abandoned after proof of concept by the end of 2025, citing poor data quality, weak risk controls, escalating costs, and unclear business value. RAND's 2024 analysis of AI project failure put the rate above 80%, roughly double the failure rate of comparable non-AI IT projects. And the figure that shows up most often in blog posts, the claim that 85% of machine learning projects fail, traces to a Gartner (2018) forecast that 85% of AI projects would deliver erroneous outcomes through 2022 because of bias, which is a claim about error rather than failure.
Why the numbers disagree
They are not measuring the same thing.
One study counts pilots, another counts projects, a third counts products that reached users. One defines failure as "no measurable P&L impact," another as "abandoned before production," another as "did not meet its stated objective." A pilot that was always meant to be a learning exercise counts as a failure under the first definition and a success under the third. A project that shipped on time and changed nothing counts as a success under the second definition and a failure under the first.
Treat the range as the real finding. Somewhere between two thirds and nineteen twentieths of enterprise AI work does not produce what it was funded to produce, under most reasonable definitions, across multiple independent measurements.
The more useful observation sits underneath the percentages, and it is the reason this article exists. When these studies describe where the work broke down, they overwhelmingly describe conditions that were already true before the project started. The data was not available. The workflow had no owner. The business case did not survive contact with finance . Those are not things that went wrong during delivery. They are things that were already wrong at selection and stayed wrong.
Failure looks like an execution problem because that is where it becomes visible
Organizations are heavily instrumented for the decision to stop and almost entirely uninstrumented for the decision to start. Every cause in the postmortem literature sits downstream of that one gap.
Read enough of those postmortems and the causes converge: data readiness, executive sponsorship, no production pathway , treating AI as an IT project rather than a business change. Each of those is real. Each is also a symptom with an earlier parent.
Walk one backward. A stalled pilot gets reviewed in month five. The review finds that the data needed to make the feature useful lives in a system the team does not have access to, and that the access request is sitting with a team that has no reason to prioritize it. That gets written down as a data readiness failure.
Back up one step. The access problem was knowable in week one. Nobody checked, because checking was not anybody's job at that point.
Back up again. The idea entered the backlog after a demo that impressed a senior person. Between that demo and the first sprint, no one was accountable for deciding whether to start. There was a process for stopping the work, several in fact, and every one of them required somebody to volunteer a negative opinion about a project that already had a sponsor.
So the failure that originated at selection gets discovered at delivery, and the postmortem names the place where it surfaced instead of the place where it happened. Which raises the practical question: what does an idea that will fail look like on the day it enters the backlog?
The four shapes of an idea that will not survive
Bad AI ideas are not random. They arrive in four recognizable forms, each with a one-line tell, and once you can name them you will find several sitting in your own backlog right now.
The demo with no owner
Somebody built something impressive over a weekend. It is impressive. Ask who would use it on a Tuesday and the answer is a department rather than a person, or a persona rather than a name.
The tell: no individual's week gets worse if this never ships.
The problem the business already decided to tolerate
The pain is real and everyone agrees it is real. It has also been real for six years, nobody is funded to fix it, and the workarounds are mature. An AI solution to a tolerated problem still has to displace a workaround people are comfortable with and a budget line that does not exist.
The tell: there was no attempt to fix this before AI made it feel newly fixable.
The task where being wrong is expensive and review is not free
The model gets it right most of the time. The cases where it is wrong carry real cost, so a human checks the output. Now measure the checking. If verifying the answer takes a meaningful fraction of the time it would have taken to produce the answer, the economics break at the review step, not the model step, and no amount of accuracy improvement fixes that.
The tell: the business case assumes review is instant and free.
The workflow that is already broken
The process has undocumented exceptions, three people who know the real rules, and a handoff that only works because someone chases it. Automating it does not remove the mess. It makes the mess run faster, at higher volume, with less visibility into where it went wrong.
The tell: nobody can describe the current process end to end without saying "it depends."
The triage that takes an hour and saves a quarter
Eight questions, one room, one hour. The filter is short on purpose, because a filter that takes a week is a project, and a filter that becomes a project does not get run.
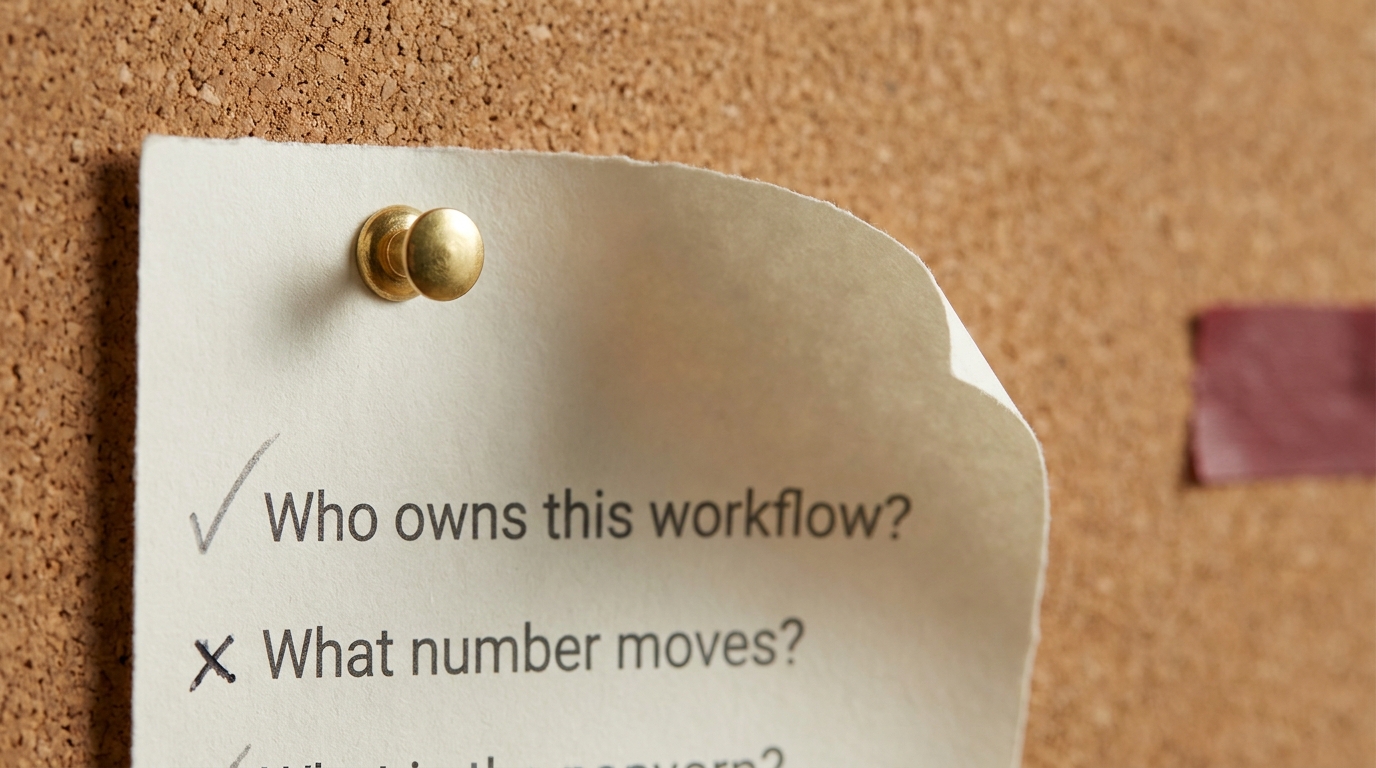
Each question is answerable with evidence rather than opinion. The point is not to score the idea. The point is to find out whether anyone can answer at all.
| Question | What a good answer looks like | What a red answer means |
|---|---|---|
| Who owns this workflow? | A named person whose week measurably improves | If it is a department, nobody will adopt it |
| What number moves? | An existing metric with a current value | If the metric has to be invented, there is no before-state |
| What is the current value of that number? | Measured, not estimated, and available today | Without a baseline you cannot prove the outcome later |
| What does being wrong cost? | A bounded, stated consequence | If nobody has thought about it, the review burden is unpriced |
| What does reviewing the output cost? | Minutes per item, from someone who would do the reviewing | If review is assumed free, the economics are untested |
| Is the data available today? | Accessible now, by this team, in this quarter | "After the migration" means this is not the idea to start |
| What happens if we do nothing? | A specific consequence with a timeframe | If nothing happens, the idea is optional and will be deprioritized anyway |
| Who can kill this, and on what evidence? | A named person and a stated condition | Without kill criteria, the project ends by exhaustion instead of decision |
Run it with the people who would actually do the work, not with the people who would approve it. An hour is usually enough, and most of that hour is spent discovering which questions nobody can answer.
A failing score has two different meanings
This is the part most kill processes get wrong. A bad idea and a good idea with a missing precondition look identical on the scorecard and should be handled completely differently.
If the workflow has no owner and no number moves, that is a bad idea. Bin it and say so.
If everything holds except that the data lands after a platform migration in two quarters, that is not a bad idea. That is a good idea with a date. Write the re-entry condition down, name who checks it, and put it back in the queue. Ideas that get killed without a re-entry condition come back anyway, six months later, with the same gaps and a new sponsor.
The filter has limits. It is a filter, not a forecast. Ideas that pass can still fail on execution, and occasionally an idea that fails the filter turns out to be right for reasons the questions do not capture. What it catches reliably is the idea that nobody has examined, which is the overwhelming majority of what it will see.
What the ideas that survive have in common
The surviving tenth is never the impressive one. It is usually a specific, unfashionable task with a number already attached to it.
The common characteristics are consistent. Scope is bounded to something a small team can ship inside a quarter. The owner feels the pain personally rather than representing a group that feels it. A before-state was measured before anyone wrote code. The cost of a wrong answer is tolerable or cheaply caught. And the path to production exists on day one, meaning the systems it needs to touch are systems this team can already touch.
Two illustrative shapes, both common:
A support team with a measured median first-response time and a queue where most tickets fall into a small set of categories the team already recognizes. The number exists, the owner is the support lead, the failure mode is a wrong draft that a human deletes in seconds, and the tooling already has an API.
A quality assurance process where writing test cases for a release consumes a known number of hours, tracked because someone has to staff it. Same structure. Real baseline, named owner, cheap review, low blast radius, and the systems involved are already accessible.
Neither of those would survive a pitch meeting against something more ambitious. That is part of why they work. Both are the kind of thing that ships and then gets extended, which is how AI capability actually accumulates in a company.
The same mistake, one technology cycle earlier
None of this is new, which should be slightly alarming. What is new is that the thing which used to stop bad ideas has been removed.
The machine learning era produced the same failure profile for the same structural reason. The postmortems from that period name data quality, deployment gaps, missing MLOps, and organizational resistance. All downstream. The projects that failed generally failed because somebody picked a problem the business did not need solved, and everything after that was consequence.
Building used to be expensive, and that expense was itself the filter. When a machine learning project meant hiring data scientists, labeling a dataset, and spending six months before anyone saw a result, the cost of starting forced a conversation about whether to start. The conversation was not always a good one, but it happened, because somebody had to sign for it.
That filter is gone. A convincing prototype now takes an afternoon. The cost of starting has collapsed to nearly nothing, and the cost of finishing has not moved at all. Production still needs evaluation, monitoring, error handling, security review, change management, and someone to own it at 3am. What collapsed was only the part that used to trigger scrutiny.
So companies now generate far more AI ideas, validate them far less, and discover the cost much later. The pre-build filter used to be enforced by economics. Now it has to be enforced deliberately, by a person, in a meeting nobody wants to call.
Saying no has to be a decision the organization makes
The reason bad ideas survive reviews is rarely that nobody noticed. Usually three people noticed and none of them said it out loud, because individual refusal is expensive in a way individual enthusiasm is not.
Say yes to a bad idea and you share the failure with everyone else who said yes. Say no to an idea someone senior likes and you own the objection personally, immediately, and alone. If it later succeeds elsewhere, you own that too. The asymmetry is obvious to everyone in the room, which is why the room stays quiet.
That is an organizational design problem, not a courage problem, and it has organizational fixes.
Define kill criteria before work starts , in writing, agreed by the sponsor. "If we cannot access the source data by week three, we stop" is a decision the group made in advance, and executing it later is administration rather than confrontation.
Give the decision to start a named owner, the same way the decision to ship has one. Somebody signs for entry into the backlog.
Keep a written record of what was declined and why. This is the piece most teams skip, and it is the one that compounds. A visible list of rejected ideas with reasons turns saying no from an event into a practice, and it stops the same idea returning every two quarters with fresh packaging.
Review on a standing cadence rather than by exception. An idea that has to be actively killed will not be. An idea that has to be actively renewed usually gets an honest assessment.
Where prompt engineering earns its keep
Prompt craft has real value. Doing it before the decision is what strips the value out.
Once an idea has survived triage, prompt and context design becomes real engineering work and deserves real investment. Not the afternoon-of-fiddling version. The version with an evaluation set built from actual failure cases, versioned prompts, regression tests that run before a change ships, and measurement of the specific behavior the business cares about rather than a general sense that outputs look better.
That work is hard, and the vendor guidance on it is good. The difference is what it is attached to. Applied after selection, careful specification is how a validated idea becomes a reliable system. Applied before selection, it is a way of feeling productive about a question that has not been asked.
Decide, then specify. Doing it in that order costs nothing. Doing it in the other order costs a quarter.
What the ideas you did not kill actually cost
Most accounting of failed AI projects stops at spend. Tokens, licenses, contractor days, some fraction of salary. That number is usually small enough to absorb, which is exactly why the failures continue.
The real cost is the part nobody invoices.
Four engineers on a doomed pilot for a quarter is a quarter of that team's output, permanently spent. The roadmap slot that idea occupied was not available to anything else, and roadmap slots are the scarce resource in most organizations. The measurement infrastructure the team built for a workflow that did not matter is infrastructure that was not built for one that did.
Then there is the credibility. Every AI project that demos well and changes nothing raises the evidentiary bar for the next one. The finance partner who funded the last three asks harder questions about the fourth, which is rational. But the fourth one might be the good one, and it now has to clear a bar set by the failures of the first three. Organizations that have burned their credibility on unexamined ideas end up unable to fund the examined ones.
Killing nine ideas is what makes the tenth affordable and staffable, and what makes the room believe you when you bring it.
Key takeaways
- The published failure rates for AI projects run from roughly 70% to 95% depending on the definition, and the causes they name are almost always conditions that were already true before the project started.
- Refining a prompt is the cheapest available substitute for deciding whether the idea deserves a build, which is why it is the thing that gets done first.
- Four shapes predict failure reliably: no named owner, a tolerated problem, an unpriced review burden, and a workflow that was already broken.
- An hour of structured triage with the people who would do the work catches the overwhelming majority of ideas that should not proceed.
- A bad idea and a good idea with a missing precondition need different outcomes. One gets binned, the other gets a written re-entry condition.
- The cost of the ideas you do not kill is measured in roadmap slots and credibility, not in API spend.
If your backlog is longer than your capacity and you are not sure which parts of it deserve a build, that is the problem worth solving first. The AI Readiness Snapshot is a free 30-minute call that maps where AI will actually move a number in your operation, and which of your current ideas are waiting on a precondition rather than a decision.