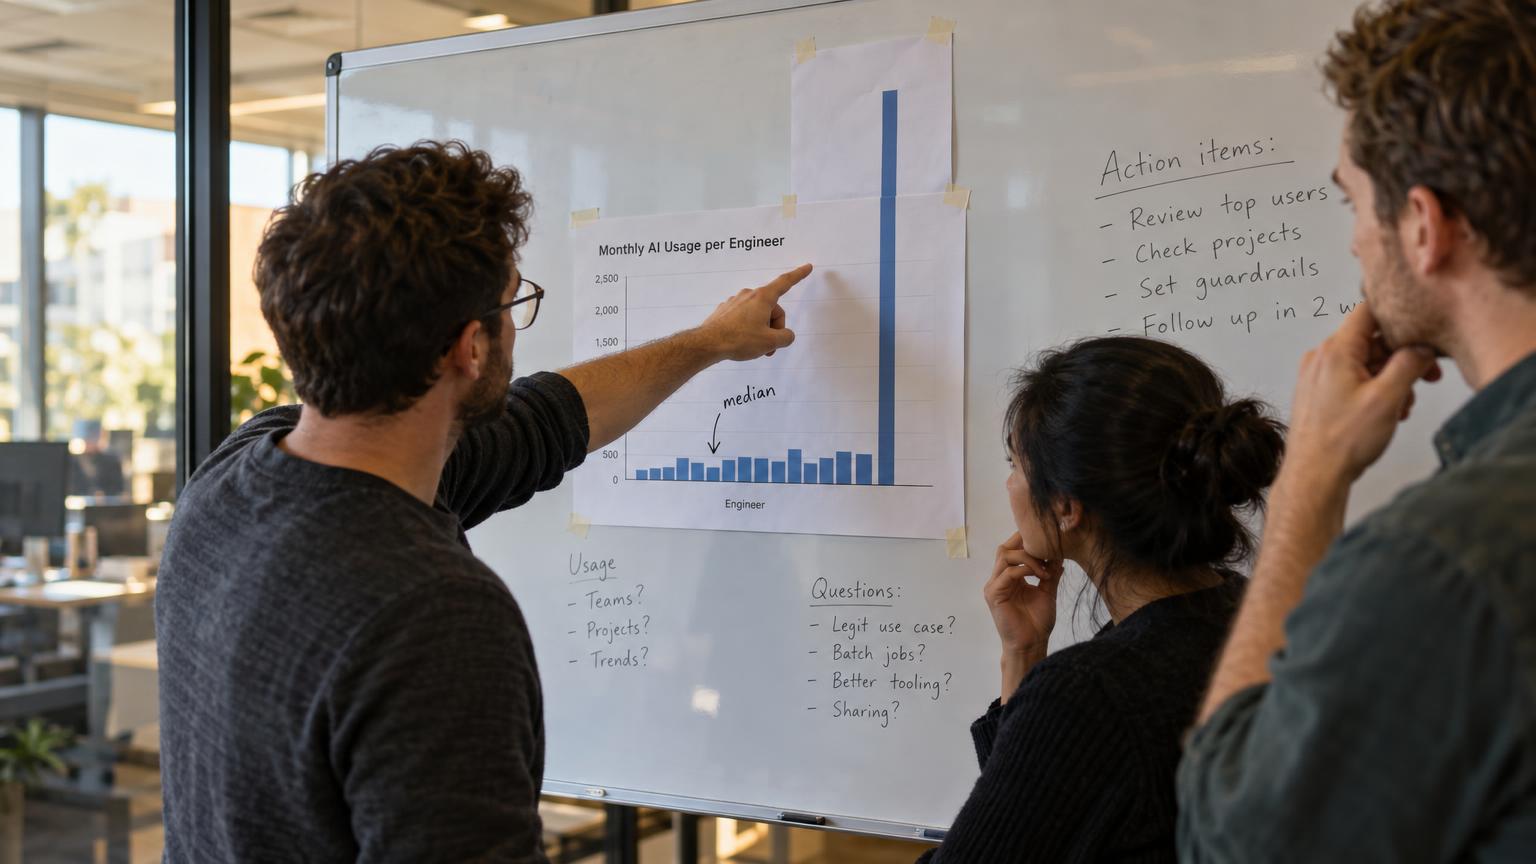
In April, the Claude that Anthropic's own employees used would have cost more at list prices than the company paid them that month. Business Insider reported the detail on November 1, 2026, citing Anthropic's S-1 filing : the retail value of internal Claude usage exceeded monthly employee compensation (excluding stock awards), and internal usage grew more than 250-fold between January and September. OpenAI has published a similar figure. Daily token use, valued at API prices, passed $600 for its median researcher and $7,000 at the 90th percentile.
Those numbers get forwarded to CFOs with one question attached: is that where we are heading? At most companies nobody can answer, because nobody has set a number for what one engineer's AI usage should cost. Finance sees a token invoice that doubled in a quarter. Engineering sees agents that finally do real work. Without a model in between, the first budget decision tends to be a blunt cap.
This article builds that model. It separates the headline numbers from what you actually pay, sizes AI spend per engineer as a band instead of a single figure, compares three ways to govern it, and ends with what to send finance so the line item reads as capacity rather than overhead. The whole argument fits in six words: budget the spread, not the average.
The $600-a-day figure is retail value, not a bill
Two different numbers hide behind the phrase "AI spend," and most budget arguments go wrong because people use them interchangeably.
Retail value is the tokens an engineer consumes multiplied by the list API price of the model that served them. It measures how hard someone is using AI. Anthropic and OpenAI run their own models on their own infrastructure, so for them a "$7,000 day" is a measure of usage intensity, not cash leaving the building.
Cash cost is what your company pays. It is a stack: seat fees, credits included with those seats, overage billed at list or negotiated rates, and discounts for cached and batched tokens. Two engineers with the same retail value can produce very different cash costs depending on which plan they sit on and how their requests are routed.
The distinction matters most at the exec table. A CFO who reads "$7,000 a day" and sets a cap off that number is budgeting against a figure that does not describe your bill. A CTO who answers "we are nowhere near that" without a number of their own has not answered the question either. So what does a real bill look like? The public data is thinner than the headlines, but it exists.
What companies actually spend per head today
The best public benchmark comes from card and invoice data, not vendor surveys. According to the Ramp AI Index (November 2026), the median company paying for AI spends about $16 per employee per month. The top 10% of those companies spend around $800 per employee, and the top 1% spend roughly $10,200. TechCrunch, reporting on the same data on November 6, 2026, put median firms at $12 to $15 per employee per month and the top 10% at $600 to $1,000.
Two cautions before you compare yourself to those figures. First, they are averages across every employee, including people who never open a coding agent. Engineers running agents all day sit far above their company's median. Second, Ramp counts what flows through cards, invoices and ACH, so it captures cash cost, not retail value. That makes it the right comparison for your budget and the wrong one for the Anthropic headline.
If your whole company sits near the Ramp median while your engineers run agents daily, your engineering spend per head is probably already several times the company average. That is normal. Being above $16 tells you very little. What matters is whether anyone understands and governs the spread inside your engineering team.
The spread between users matters more than the average
Usage of coding agents is not evenly distributed, and that unevenness is what breaks most budgets. OpenAI's own figures imply roughly a 12x gap between its median researcher and the 90th percentile. You will not see the same absolute numbers, but you will almost certainly see the same shape.
GitHub described the problem from the vendor side when it announced the move to usage-based billing for Copilot (GitHub blog, April 27, 2026). Under the old model, a quick chat question and a multi-hour autonomous coding session could cost the user the same amount, and GitHub said the premium request model was "no longer sustainable." The same skew that strained GitHub's flat pricing now lands on your budget.
In practice, most engineering teams split into a few usage profiles:
- Completion-first users mostly accept inline suggestions and occasionally ask a chat question. Their usage often fits inside a seat's included allowance.
- Chat-and-review users use AI for explanations, refactors and code review several times a day.
- Agent-heavy users hand multi-step tasks to agents that read large parts of the repository and iterate for minutes or hours at a time.
- Background agents run in CI, on schedules, or in response to tickets with no human watching the meter. This is often the fastest-growing line and the least visible one.
A flat average budget fails in both directions. It overfunds the first group and throttles the third, and the third group usually includes the engineers producing the most.
That is the core rule of this whole exercise: budget the spread, not the average.
Seats, pooled credits and metered tokens: what you are buying
Most teams buy AI through a mix of seat plans and direct API usage , and the two behave differently once usage grows. The clearest current example is GitHub Copilot, because GitHub publishes its rules in detail. The same arithmetic applies to any tool or API account: find the included allowance, then price what sits above it.
Since June 1, 2026, Copilot has replaced premium requests with GitHub AI Credits, consumed on input, output and cached tokens at each model's published API rates. Base plan prices did not change (GitHub blog, April 27, 2026). According to GitHub Docs, Copilot Business costs $19 per user per month and includes 1,900 AI credits per user, and Copilot Enterprise costs $39 per user per month with 3,900 credits. One AI credit equals $0.01. On Business and Enterprise, each license contributes its credits to a shared pool at the billing-entity level, and usage beyond the pool is billed separately. Inline code completions do not consume credits.
| Billing model | Example | What the price includes | What happens past the allowance | Best fit |
|---|---|---|---|---|
| Individual seat | Copilot Pro $10, Pro+ $39, Max $100 per month | A personal monthly credit allowance | Additional usage billed in credits, or stopped by a budget | Individuals and small teams |
| Business seat with pooled credits | Copilot Business $19, Enterprise $39 per user per month | $19 or $39 of credits per user, pooled across the organization | Overage billed per token from the pool | Teams with uneven usage |
| Direct API, metered | Pay per million input and output tokens | Nothing up front | Every token billed, with cache and batch discounts on eligible traffic | Agents, internal tools, background jobs |
| Enterprise commitment | Negotiated annual spend with a provider | Committed volume at agreed rates | Depends on the contract | Large, predictable volumes |
For an agent-heavy engineer, the seat price is a floor, not a ceiling. Datafloq noted another change that matters here: GitHub removed the fallback that let users who exhausted their premium requests keep working on cheaper models, so heavy users now hit overage directly instead of degrading quietly.
Anthropic has followed a similar path for enterprise customers. Spiceworks reports that by April 2026 Anthropic had moved enterprise customers from flat-rate seats with fixed caps to a model where the seat fee covers platform access and tokens are billed at API rates.
Three ways to budget AI spend, and when each works
Once you accept that usage is skewed and billing is metered, you have three practical ways to govern the budget. Each one fails in a different way, so the choice depends on how uneven your team's usage is and who will own the alerts.
| Criteria | Flat per-seat budget | Pooled team budget | Metered with alerts |
|---|---|---|---|
| How it works | A fixed dollar amount per engineer per month | One monthly envelope per team, shared across its members | Pay for actual use, with alerts at set thresholds and an owner who acts on them |
| Predictability for finance | High | Medium to high | Medium |
| Handles skewed usage | Poorly | Well | Well |
| Admin effort | Low | Low to medium | Medium |
| Typical failure | Heavy users stall mid-sprint when they hit their cap | One team's background agents drain the pool unnoticed | Alerts fire and nobody reads them |
| Best for | Teams where most usage is completion and chat | Teams of 10 to 100 with a few heavy agent users | Organizations running agents in CI or production workloads |
Pick a flat per-seat budget when nearly everyone sits in the completion-first and chat-and-review groups, and predictability is the main goal. Pick a pooled team budget when a handful of engineers drive most of the usage, which is the common case once agents are adopted. Copilot Business and Enterprise already pool credits natively, so this model costs little to run. Pick metered with alerts when background and production agents make up a large share of spend, because those workloads need per-key or per-workload limits, not per-person ones.
Hard caps versus soft limits
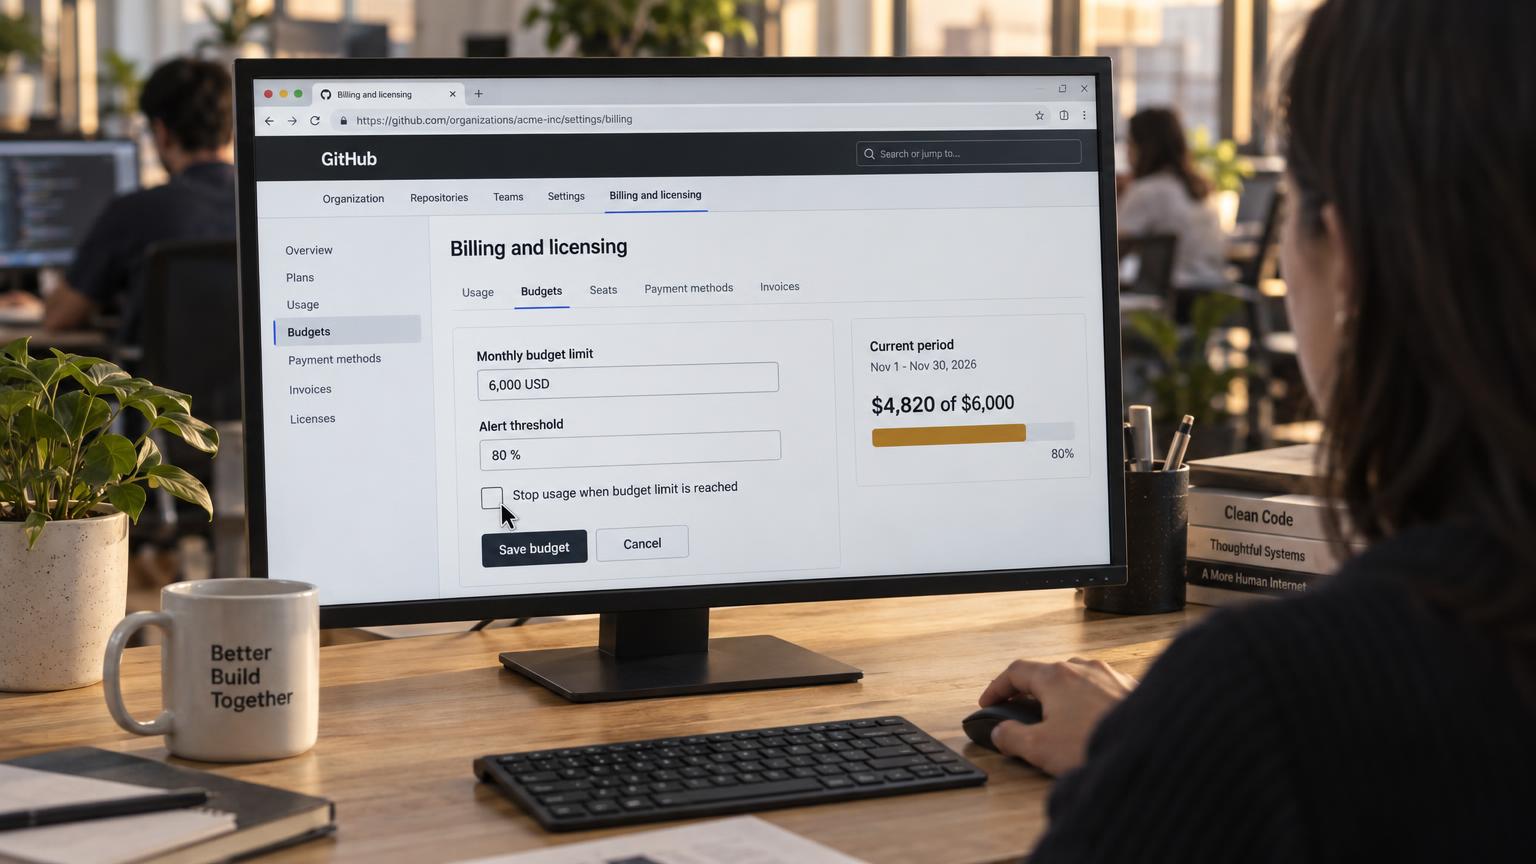
The tooling for both exists. GitHub Docs describes a budget you can set to $0 with "Stop usage when budget limit is reached" enabled, which blocks any usage beyond the included credits. Ramp's AI Spend Management lets finance set soft limits on individual API keys. A hard cap protects the budget and stops the work at the same moment. A soft limit protects the work and relies on someone to respond. Name that person in writing before the first alert fires. For interactive engineering use, soft limits with a clear owner usually cost less than the sprint time a hard stop wastes.
A worked AI budget for a 50-engineer team
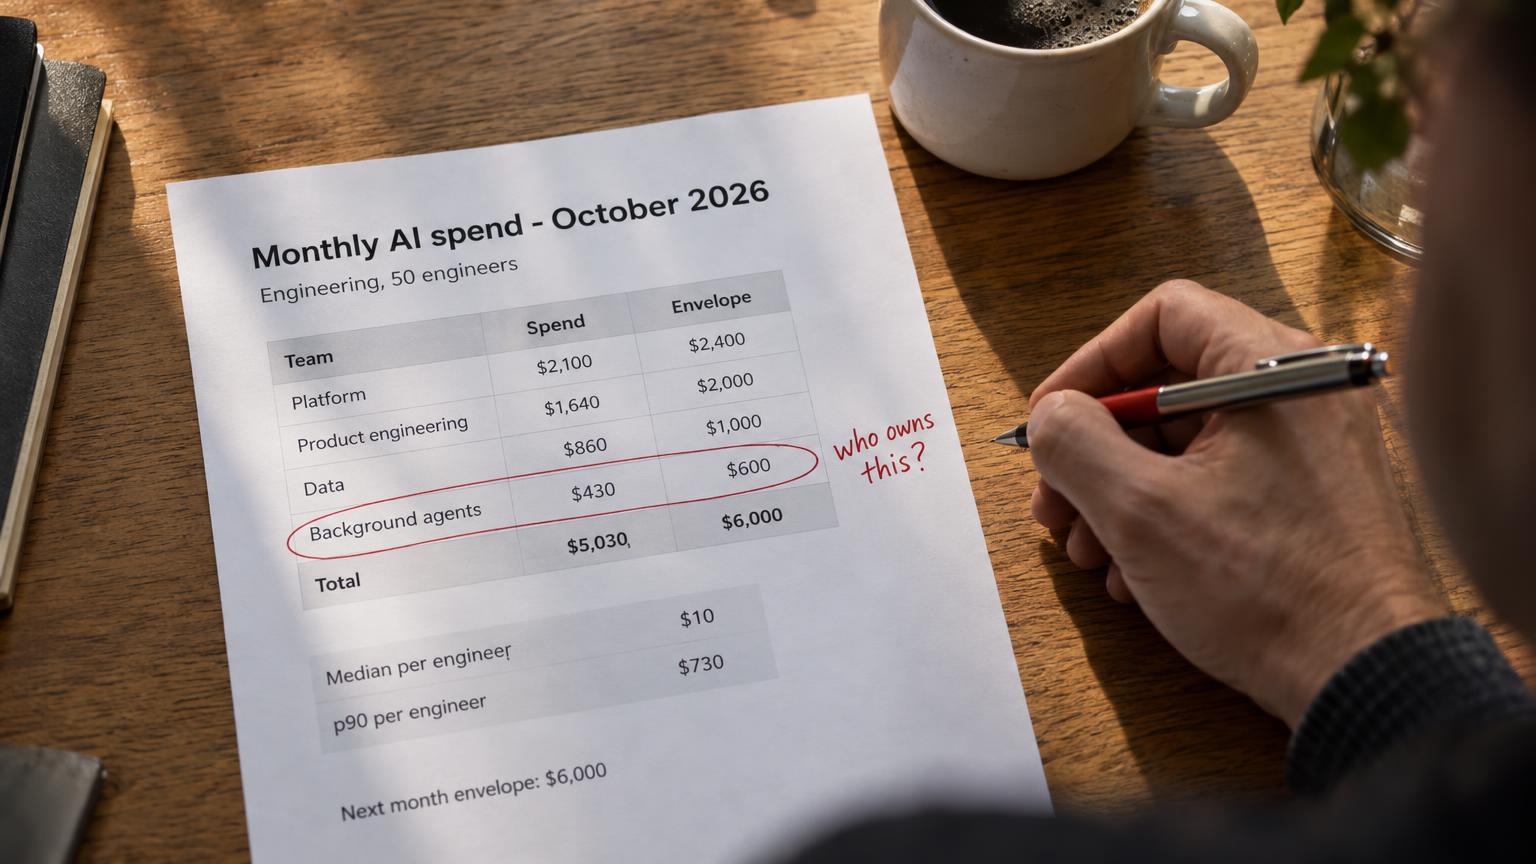
The model below lands at about $100 per engineer on average, and about $730 for a heavy agent user. The numbers are an illustrative model, not a benchmark. Replace each assumption with your own usage data. The point is the method: segment, price, subtract the allowance, apply levers, add a buffer.
- Segment the team. Assume 30 completion-first or light chat users, 15 regular agent users, and 5 heavy agent users.
- Price the seats. 50 Copilot Business seats at $19 equals $950 per month. Those seats include 50 x 1,900 = 95,000 pooled credits, worth $950 of usage.
- Estimate monthly usage at list rates. Assume $10 per light user, $150 per regular user, and $1,200 per heavy user. That is $300 + $2,250 + $6,000 = $8,550 of usage per month.
- Subtract the allowance. $8,550 minus the $950 pool leaves $7,600 of overage. Cash cost is $950 in seats plus $7,600 in overage, or $8,550 per month, about $171 per engineer on average.
- Apply routing. Assume half of regular-tier usage and 30% of heavy-tier usage can move to a model priced at one fifth of the frontier rate. That saves $900 on the regular tier and $1,440 on the heavy tier.
- Apply caching. Assume prompt caching on repository context cuts the remaining regular and heavy usage by 20%. That saves about $1,180.
- Read the result. Monthly usage falls to about $5,030, or roughly $100 per engineer on average. By segment, a light user costs about $10 of usage (inside the seat), a regular user about $72, and a heavy user about $730.
- Add a buffer. A 20% buffer gives a monthly envelope of about $6,000, or $72,000 a year for the team.
Now the same team under each governance model:
- Flat per-seat: a $120 cap per engineer looks generous on average, but every heavy user hits it in the first week. Either the cap is raised for five people, which makes it a pooled budget in disguise, or those five lose their most productive tool for most of the month.
- Pooled team budget: a single $6,000 envelope absorbs the spread. The alert that matters is the pool reaching 80% before the 20th of the month, which usually means a background agent or a new workflow, not a person.
- Metered with alerts: interactive use sits in the pool, and each CI or scheduled agent gets its own API key with a soft limit. The owner of each key gets the alert, not a central inbox.
Back to the title question, then. For this team, too much means one of two things: spend above the band the usage profile predicts with no change in what the team ships, or background agent spend growing faster than the work it is attached to. A $730 heavy user, on their own, is neither.
Levers that lower cost without capping your best engineers
Caps are the bluntest tool you have. The levers below lower the bill and leave the heavy users productive.
- Route by task, not by habit. Accenture's CIO guide to AI tokenomics found that 90% of more than 9,000 tasks it studied did not require a frontier model and recommends routing only the roughly 10% of workloads that need frontier capability to those models, enforced at a gateway rather than left to each developer. Accenture also names "frontier by default" as a root cause of overspend: people pick the most capable model even when a cheaper one would do.
- Cache the context you resend. Coding agents resend large amounts of repository context on every turn. CloudZero's LLM API pricing comparison puts cached input reads at roughly 10% of the standard input rate across major providers, and batch processing at 50% off for asynchronous jobs.
- Control output length. CloudZero also notes that output tokens cost five to six times as much as input tokens everywhere, so limiting verbose responses often saves more than switching providers.
- Audit background agents monthly. Agents triggered by schedules and CI keep running after the project that needed them ends. A monthly review of idle and duplicate jobs is cheap and often finds real money.
McKinsey (July 2026) reports that companies that manage AI consumption thoughtfully can save 20 to 30% on their AI costs, and that only 20 to 25% of companies have mature AI FinOps practices in place. Most teams are not starting from an optimized baseline, so the first round of savings usually comes quickly.
What to send finance with the invoice
Finance has heard the ROI argument already. What it needs each month is a one-pager that shows the spend is understood, governed and attached to work. A useful version fits on a single page:
- Spend by team and by model tier, against each team's envelope.
- The per-engineer distribution: median, 90th percentile and the top five users, with one line on what the heavy users shipped.
- The share of spend on cached, routed or batched tokens, which shows the levers are switched on.
- Background agent spend, separated from interactive spend, so growth in unattended workloads is visible on its own.
- Two or three output signals next to the spend, such as merged pull requests, tickets closed or review turnaround, measured the same way every month. Present them as context, not as a return calculation.
- Next month's envelope, and the one decision you need from finance.
Start with showback before chargeback. Accenture reports that showback dominates today and only 7% of companies use a chargeback model for AI costs, while naming chargeback as the strongest predictor of cost optimization in its research. Showback gets teams used to seeing their numbers. Chargeback, once the reporting is trusted, makes each team weigh its own spend.
Key takeaways
- Retail token value and cash cost are different numbers. Budget against cash cost, and treat frontier-lab headlines as a measure of usage intensity.
- Set a per-engineer band by usage profile, not a single average. The spread between light and heavy users is the thing your budget has to absorb.
- Pooled team budgets fit most engineering teams once agents are in use. Add metered keys with soft limits for background and CI agents.
- Routing, caching and output limits lower the bill without throttling your most productive engineers.
- Report spend next to a few output signals each month, so finance reads the line as capacity, not cost.
If you want a second pair of eyes on your team's numbers, book a free 30-min readiness call . In an AI Readiness Snapshot we help you sort your engineers into usage profiles, size the per-engineer band, and choose the governance model that fits how your team actually works.