A codebase nobody has opened since spring still has to answer a search the second someone opens it again. Until then, it earns nothing. Cursor runs that problem at enormous scale, and how it priced the idle majority of its index is the most useful part of its story. Turbopuffer's published Cursor case study reports a 95% reduction in vector database costs after the move to Turbopuffer. That figure covers vector database spend only, for one company's workload. It is not a forecast for anyone else.
The transferable lesson is narrower and more useful: pay fast-storage prices for what people are searching, not for everything you have stored. When search infrastructure matches how people really access data, the economics of an AI product change. The question for your team is how to make more of the business's knowledge searchable without letting retrieval costs grow faster than the value the product delivers. Turbopuffer can be part of that answer. It is never the whole of it, because the search layer is one component in a system that still needs ingestion, permissions, and evaluation.
What Turbopuffer does, and what it leaves to you
Turbopuffer is a managed search engine for AI applications. It combines semantic (vector) retrieval, BM25 keyword search, and attribute filters over data kept in object storage, so one query can find passages by meaning, match exact terms, and respect conditions such as customer, product, or date.
Is it a vector database? It stores and searches vectors, but calling it only a vector store undersells it. Keyword ranking with BM25 matters in business data, where an error code, a contract number, or a product SKU has to match exactly. Namespaces let you keep separate indexes for separate tenants or projects. Turbopuffer also offers native embeddings, billed by tokens, so you don't always need a separate embedding provider.
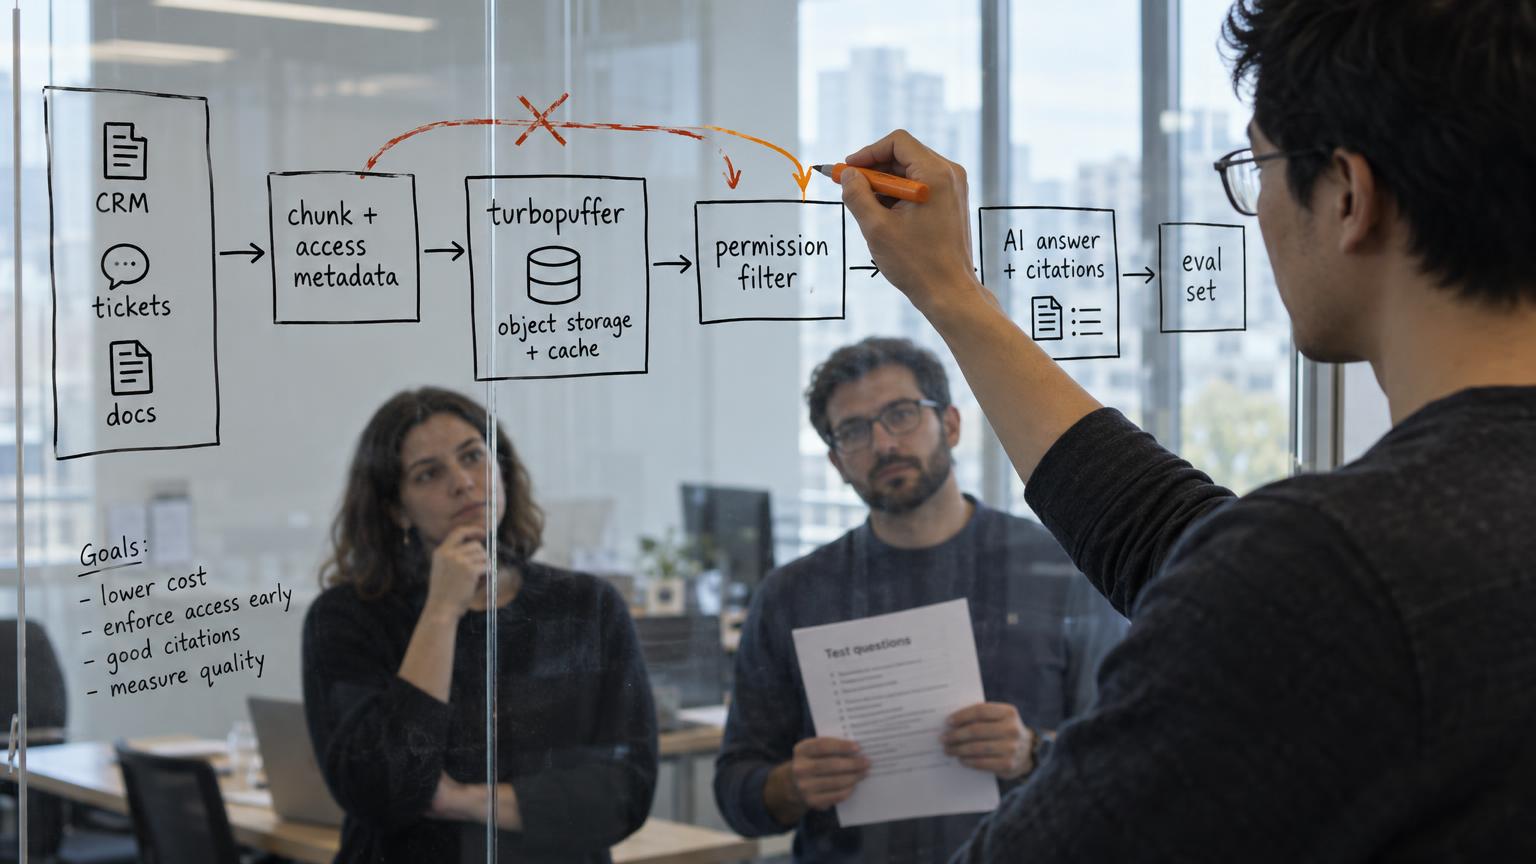
What it doesn't do matters more for your budget. It doesn't connect to your CRM, ticketing system, or document store. It doesn't decide how documents are split into searchable chunks. It doesn't know which employee may see which file. Nor does it write answers or check whether one is correct. A search engine is not a complete AI assistant , and a budget that treats it as one will be short by most of the engineering.
Turbopuffer's documentation also describes native model-based reranking. Its changelog still labels the September release as a private beta, so treat it as a roadmap item rather than something to design a project around today.
Why the architecture can lower cost, and when it won't
The saving, where there is one, comes from where the data sits. Turbopuffer keeps data in object storage (the S3 or Google Cloud Storage class of service) and caches the namespaces that are actively queried in memory and on NVMe drives. You pay fast-storage prices for the active set and object-storage prices for everything else.
Cursor's workload shows why that matters. Its users have many codebases indexed, and only some of them are being worked on at any given moment. An inactive repository still needs to be searchable, but it doesn't need to sit in memory all day waiting for a query that may come next week. When a large share of your data is quiet most of the time, separating "stored" from "hot" is where savings come from.
The same design has costs, and Turbopuffer states them in its Tradeoffs documentation:
- Cold queries are slower. When data isn't cached, a query goes to object storage and rehydrates the cache. Turbopuffer says rare queries in this state can take hundreds of milliseconds, and recommends prewarming namespaces so users don't see it.
- Writes take longer to commit. Turbopuffer puts writes at up to 200ms, with high throughput per namespace.
- Small workloads aren't the target. There is no free tier and no open-source edition.
None of this means every alternative keeps all data in RAM, so be wary of blanket cost comparisons. Pricing models differ a lot between vendors (some bill for capacity, others for usage). Savings depend on your workload, and the shape of your access pattern decides most of it.
Reading the Cursor example without overgeneralizing
Cursor uses Turbopuffer for semantic code retrieval, according to Turbopuffer's case study and a Google Cloud customer story. The case study reports a 95%, or 20x, reduction in vector database costs. It does not claim that Cursor's total infrastructure or AI spend fell by that amount, and you shouldn't repeat it that way in an internal business case.
The case study also reports scale of more than 100 billion vectors across more than 10 million namespaces. Those are the figures the case study reports. They are not a live count of Cursor's index, and they don't describe its size when it migrated in November 2023.
What carries over is the mechanism, not the number. Cursor's data is split naturally into many namespaces, and access is concentrated on a minority of them. Your saving, if there is one, depends on how much of your corpus is active, how many queries you run, how often content changes, and what you pay for search today. A team whose entire index is queried constantly won't see the same effect.
Three places it could fit in your product
These are proposed applications, described to show where the search layer ends and the rest of the system begins. They are not completed Advantage Works deployments.
An internal knowledge assistant
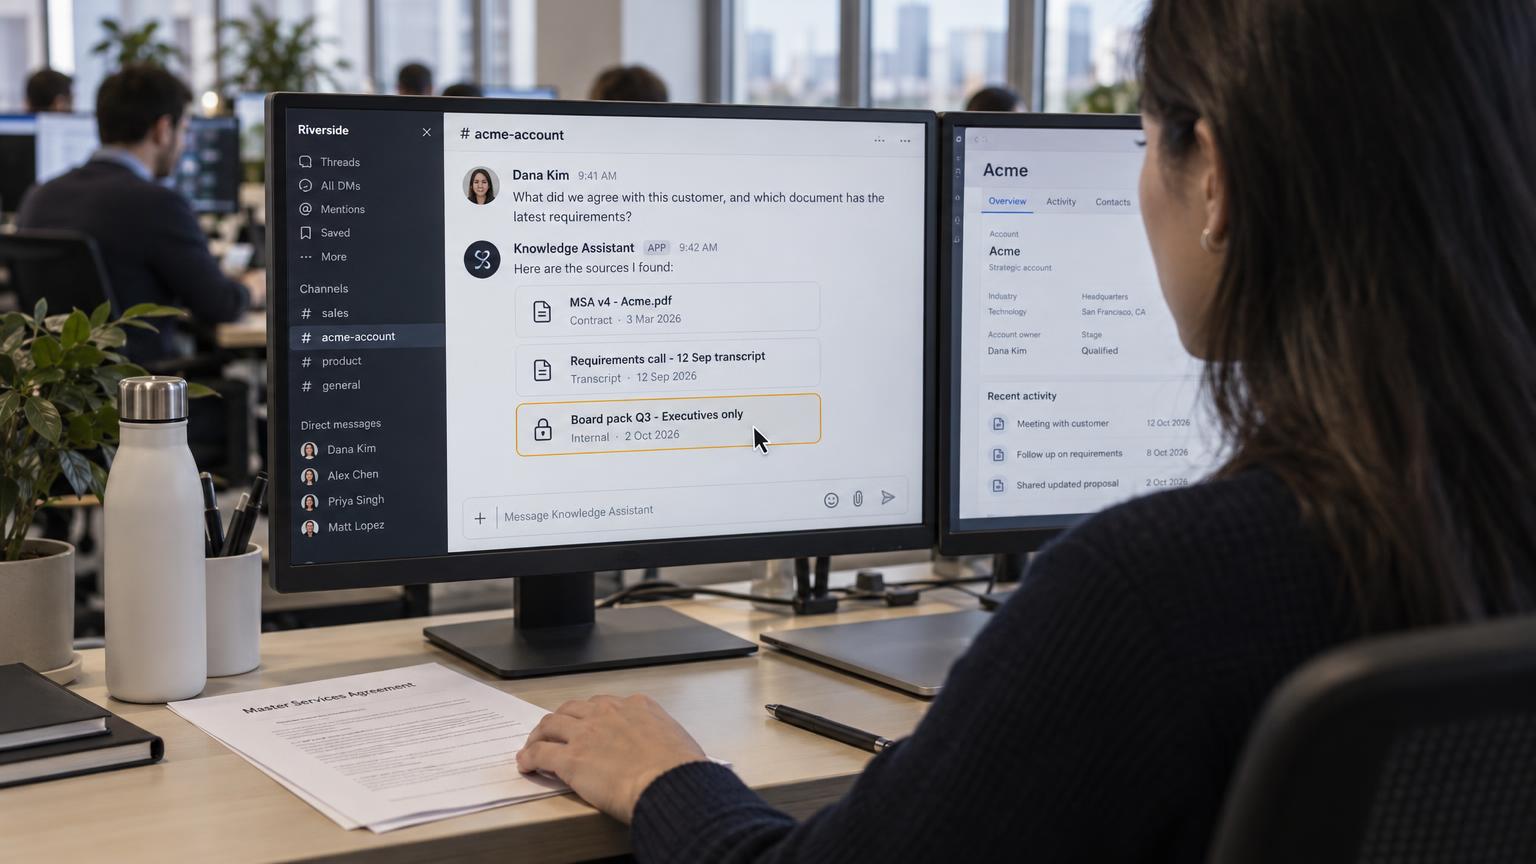
The question an account manager asks on a Monday morning is "What did we agree with this customer, and which document has the latest requirements?" To answer it, you would index approved documents, call transcripts, and customer records, then run hybrid retrieval limited to what that person is allowed to see.
The value is less time spent searching and evidence the user can open and check. The design point that matters most is authorization. Turbopuffer has no built-in document-level access control, so permissions are enforced through filters your application supplies. Every document needs access metadata at ingestion, and every query needs a filter built from the user's rights. Retrieving everything and hiding results in the interface afterwards is a leak waiting to happen, because the model may already have read what the screen hides.
A customer-support copilot
Here the question is "Has this error happened before, and what resolved it?" The copilot searches past tickets, guides, and product documentation. Semantic matching finds tickets that describe the same symptom in different words. Keyword matching catches the exact error code, product name, and version number, which Turbopuffer's hybrid search guide treats as cases where exact terms should weigh heavily.
Then comes the step teams skip. Similarity is not proof: a ticket that reads the same may describe a different version. The copilot, or the agent using it, has to confirm that the resolution matches the right product version and the customer's circumstances before recommending it.
Search inside a multi-tenant SaaS product
Each of your customers searches its own documents and gets answers with cited sources. The natural design is a namespace per customer, your application's authorization in front of it, and document-level filters inside it. Turbopuffer names naturally partitioned B2B data as one of its strongest fits.
Tenant separation solves exactly one problem. It keeps Customer A out of Customer B's data. It does nothing about a junior analyst inside Customer A seeing a board pack meant for executives. Permissions between users inside a tenant still need their own filters.
How we turn retrieval into answers you can check
All three applications fail the same way when they fail: the search returns something plausible and nobody checks it . Our work on Turbopuffer-based retrieval starts from one distinction. Finding the right evidence and using it correctly are two separate problems, and each needs its own test.
The implementation decisions follow from that. We split documents by their structure (sections, clauses, ticket threads) rather than at fixed lengths, so a citation points to a passage a person can read and verify. We attach metadata such as owner, access group, product, version, and date at ingestion, because filters can only use what was stored. We use hybrid retrieval wherever exact identifiers carry meaning. We consider reranking only after first-stage retrieval has been measured, so we know what problem it's solving.
Evaluation then runs in two layers:
- Retrieval evaluation asks whether we found the right evidence. A small, human-reviewed set of real questions, each paired with the sources that should come back. This extends Turbopuffer's own advice to build a test suite of queries with ideal results.
- Answer evaluation asks whether the response used that evidence correctly. Does each claim trace to a cited passage? Did the answer add anything the sources don't support?
Turbopuffer handles the first-stage search. It doesn't validate AI output, and nobody should present it as if it did.
What still needs engineering around the search layer
A demo can skip every item below . A product can't. Plan for this work alongside the search engine:
- Source updates: connectors for each system, and a schedule for how edits reach the index.
- Deletions and retention: a removed or expired document has to disappear from search, not linger in an old chunk.
- Permission filters: access metadata on every document, query-time filters built from each user's rights, and tests per role.
- Retrieval evaluation: a reviewed question set with expected sources, refreshed as content changes.
- Answer validation: citation support checks and unsupported-claim checks on generated responses.
- Cost monitoring: storage, writes, queries, and embedding tokens tracked against usage, so you see retrieval cost per useful answer rather than a single monthly bill.
When Turbopuffer is worth adopting
How much does Turbopuffer cost? As of October 2026, its Launch plan carries a $16 monthly minimum, plus charges for storage, writes, and queries. That entry price tells you almost nothing about your real bill. The useful comparison is total cost and measured quality against what you run today.
| Turbopuffer tends to fit | Think twice when |
|---|---|
| A large or growing corpus where only part is active at a time | The workload is small and a free or bundled option already works |
| Data that splits naturally by customer, workspace, or repository | Latency budgets can't absorb occasional cold queries |
| Search that needs semantic, keyword, and filter conditions together | You need self-hosting from an open-source edition |
| A team ready to own ingestion, permissions, and evaluation | Nobody owns the engineering around the search layer |
Run the benchmark on your own data. Measure relevant-source retrieval on your question set, latency including cold queries, the operational work of keeping the index fresh and permission-aware, and the full monthly cost. Storage price alone will mislead you.
The goal was never to store more vectors for less money. It is to get the right information to the right person, and to measure whether the answers are useful.
Planning an AI knowledge base or search feature? Start with a focused benchmark of your data, permissions, retrieval quality, and total operating cost. An AI Transformation Discovery sprint scopes that benchmark in one week. If you're earlier than that, book an AI Readiness Snapshot to find where search would pay off first.